From 1984 Sun Microsystems to Modern Cloud: The Complete NFS Timeline
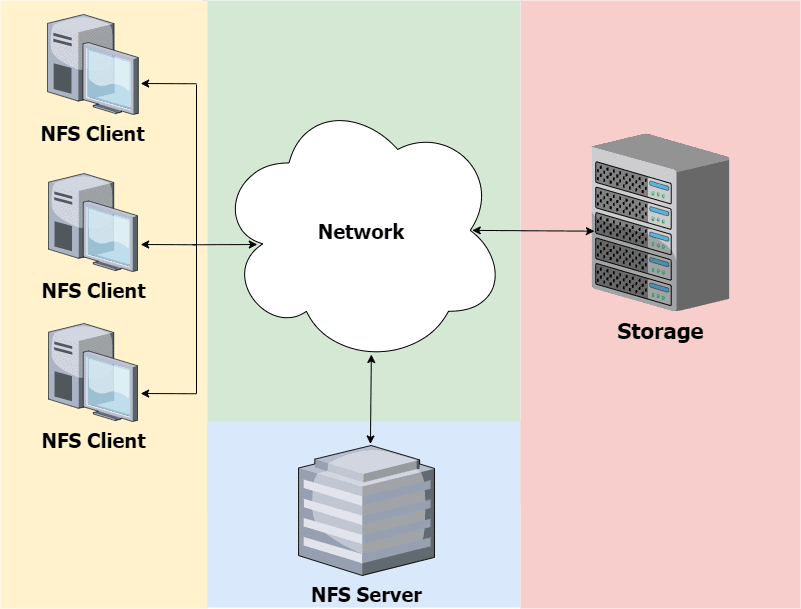
In 1984, engineers at Sun Microsystems shipped an experimental networking protocol designed to solve a mundane physical frustration: Unix workstations lacked enough local disk capacity to store independent copies of project trees and system libraries. Their creation, the Network File System (NFS), allowed remote machines to access shared directory trees across a local network as if those bytes lived on local spinning platters. More than four decades later, that modest file-sharing mechanism anchors hyper-scale datacenters, multi-tenant enterprise clusters, and Kubernetes persistent storage layers worldwide.
The system succeeded because it cleanly separated transport semantics from physical operating systems. As documented in the foundational architecture of the Wikipedia (en) Report on the internet protocol suite, NFS demonstrated how an application-layer file service could operate over External Data Representation (XDR) and Remote Procedure Call (RPC) layers to bridge fundamentally incompatible computer architectures. What began as a workstation tool now forms the structural baseline of enterprise cloud storage infrastructure.
📌 Key Takeaways:
- Foundational Origin: Sun Microsystems launched NFS in 1984, introducing an open client-server architecture that decoupled file access from physical, localized machine storage.
- Architectural Evolution: The protocol migrated from a fragile, stateless UDP implementation in NFSv2 and NFSv3 to a stateful, single-port, firewall-compatible architecture in NFSv4.
- Modern Cloud Utility: In 2026 enterprise environments, NFS remains the standard protocol for multi-pod Kubernetes storage (ReadWriteMany volumes) and managed services like AWS EFS, Google Cloud Filestore, and Azure Files.
The 1984 Sun Microsystems Breakthrough and the Stateless Bet
Before NFS arrived, sharing project files between networked computers required manual transfers using tools like FTP or Unix-to-Unix Copy (UUCP). These workflows duplicated data, introduced merge conflicts, and wasted scarce drive platters. Sun Microsystems co-founder Bill Joy and engineer Russell Sandberg set out to make the network transparent. They designed NFS around a client-server architecture where a remote server could designate local file hierarchies as mount exports, allowing remote clients to mount those remote points directly into their local virtual filesystem trees.
Sandberg and his team made a consequential engineering choice: early NFS was completely stateless. The server tracked no open files, no active file offsets, and no client connection status. If a central storage server crashed and rebooted, client workstations did not need to renegotiate state or drop sessions; they simply retransmitted the outstanding Remote Procedure Call (RPC) requests until the server responded. To translate disparate byte orders between varying central processors, such as Motorola 68000 chips and VAX minicomputers, the protocol ran atop External Data Representation (XDR), which normalized data into a machine-independent format.
That initial simplicity carried steep operational trade-offs. Statelessness made genuine POSIX compliance nearly impossible. File locking required an auxiliary, error-prone daemon called the Network Lock Manager (NLM). Early versions ran exclusively over UDP, which meant a dropped packet inside a heavily partitioned network could trigger cascading timeout loops. Furthermore, NFSv2 was locked to 32-bit arithmetic, creating a hard limit of 2 gigabytes per file that quickly buckled under enterprise database demands.
From Academic BSD Ports to the Enterprise Workhorse
Sun avoided proprietary lock-in by publishing the NFS specifications openly, licensing code to universities and commercial rivals. The protocol spread quickly through academic environments. The University of Guelph contributed an early, influential implementation to the Berkeley Software Distribution (BSD) ecosystem, extending support across diverse hardware lines like the HP 9000 series. As Unix variants matured, dedicated open-source kernels turned NFS into an operational staple. OpenBSD hardened the protocol inside multi-role network daemons, while FreeBSD later overhauled its client and server code paths to introduce full NFSv4 support, adding hardware-accelerated AES encryption to protect RPC payloads in production transit.
The release of NFSv3 in 1995 (RFC 1813) rectified the early architectural bottlenecks. It added 64-bit file offsets, removing the 2-gigabyte ceiling and allowing filesystems to scale into multi-terabyte volumes. Crucially, NFSv3 added support for TCP transport alongside UDP. TCP handled network congestion and packet loss mitigation directly, sparing the RPC layer from constant retransmission timers. It also introduced asynchronous writes, allowing the storage server to acknowledge data writes as soon as bytes hit non-volatile cache rather than forcing clients to wait for physical spindle syncs.
Network-attached storage (NAS) manufacturers quickly seized on NFSv3. Appliances from companies like NetApp built billion-dollar data storage businesses around this specific protocol, powering rendering farms, electronic design automation (EDA) software, and enterprise software compilation pipelines throughout the late 1990s and early 2000s.
Four Decades of Protocol Evolution: From Stateless UDP to NFSv4.2
The progression of NFS mirrors the broader transformation of corporate computer networks, shifting from trusted local area subnets toward secure, latency-sensitive wide-area networks and multi-tenant clouds.
| Protocol Version | Release Window | Transport & State | Defining Capabilities |
|---|---|---|---|
| NFSv2 | 1984, 1989 | Stateless (UDP only) | 32-bit file offsets, 2GB file limit, separate portmapper and lock daemons. |
| NFSv3 | 1995 | Stateless (UDP / TCP) | 64-bit offsets, asynchronous safe writes, READDIRPLUS for faster directory walking. |
| NFSv4.0 / 4.1 | 2000, 2010 | Stateful (TCP, Port 2049) | Compound RPC calls, Kerberos security, integrated file locks, Parallel NFS (pNFS). |
| NFSv4.2 | 2016, 2026 | Stateful (TCP / RDMA) | Server-side copy, sparse files (hole punching), labeled security (SELinux), NVMe integration. |

Why the NFSv4 Overhaul Broke with the Past
By the late 1990s, the stateless model was obsolete. Internet firewalls blocked the sprawling cluster of auxiliary ports demanded by NFSv3 mount daemons, lock managers, and RPC portmappers. In response, Sun Microsystems handed control of the specification to the Internet Engineering Task Force (IETF), yielding the NFSv4 protocol in RFC 3010 and RFC 3530.
The standard changed fundamentally. NFSv4 became an explicitly stateful file-sharing protocol. It eliminated secondary daemons, routing all control communication, locking mechanisms, and data transfers through a single well-known port: TCP 2049. This simple consolidation made enterprise firewall traversal straightforward.
NFSv4 also tackled latency over wide-area links. In NFSv3, opening a file, checking permissions, reading bytes, and closing the handle required four separate network round trips. NFSv4 introduced compound RPC requests, packaging directory traversal, permission verification, and read operations into a single network transmission packet. Security modernized alongside it. NFSv4 discarded simple, easily spoofed Unix user identifier (UID) passing, integrating mandatory cryptographic authentication through Kerberos and access control lists (ACLs) compatible with both Windows and Unix permissions.
Later revisions transformed capacity scaling. NFSv4.1 introduced Parallel NFS (pNFS), which separated the metadata path from the data path. Instead of forcing all I/O traffic through a single bottlenecked storage head, clients query a central metadata server for data layouts, then stream raw data stripes directly across dozens of discrete storage target servers simultaneously.
NFS in Modern Cloud Infrastructure and Container Workloads
The rise of cloud computing and containerized deployments did not displace NFS. It accelerated adoption. Object stores like Amazon S3 and Google Cloud Storage work well for immutable files, but they lack POSIX compliance. Applications cannot execute standard OS system calls, like open(), seek(), or direct directory renames, against an object bucket without complex, high-latency emulation layers.
NFS remains the fastest path to bridge that gap. Hyperscalers run massive distributed file system engines presenting pure NFS endpoints: Amazon Elastic File System (EFS), Azure Files (NFSv4.1 tiers), and Google Cloud Filestore. These managed services eliminate physical array maintenance while delivering elastic storage expansion.
Container orchestrators rely on the protocol for multi-node elasticity. In Kubernetes, local block storage plugins (like raw AWS EBS or Ceph RBD) typically mount as ReadWriteOnce (RWO), locking a storage volume to a single physical worker node. When a deployment requires hundreds of stateless application pods to read and write to the same shared repository, such as distributed WordPress installations, continuous integration pipelines, or model weights in machine learning inference fleets, operators mount NFS exports using ReadWriteMany (RWX) persistent volume claims. The kernel handles access arbitration transparently.
Performance Bottlenecks, Lock Contention, and Storage Realities
NFS provides exceptional operational flexibility, but treating a network share like local NVMe flash invites severe performance degradation if workloads are misaligned. Distributed file systems introduce transport latency and synchronization overhead that local filesystems bypass entirely.
High-throughput transactional databases demonstrate this failure mode regularly. Running production PostgreSQL, MySQL, or high-write transactional datastores directly over an NFS mount often triggers acute I/O wait spikes. Because relational databases rely heavily on strict fsync() behavior to preserve write-ahead logging integrity, every commit forces a synchronous network round-trip to the storage filer. Under high concurrency, file lock contention at the NFS client layer throttles throughput, creating the dreaded Linux uninterruptible sleep (D-state) process hangs if network connectivity drops.
NFS also introduces the risk of stale file handles (ESTALE errors). If an application caches an open file reference while a secondary client deletes or moves that underlying inode on the export server, subsequent client requests will fail abruptly. When raw sub-millisecond latency and millions of random IOPS are the dominant operational criteria, raw block storage protocols, such as NVMe over Fabrics (NVMe-oF) or direct-attached non-volatile memory, remain superior choices.
Frequently Asked Questions (FAQ)
What is the core difference between NFS and SMB/CIFS?
NFS is primarily built for Unix and Linux environments, historically emphasizing POSIX compliance and direct kernel integration. Server Message Block (SMB), originally known as CIFS, is Microsoft's native networking file protocol designed around Windows security descriptors, NT-style locking semantics, and Active Directory integration. While modern implementations run across both operating systems, NFS remains the standard for Linux server fleets and container clusters, whereas SMB dominates Windows enterprise offices.
Why do Kubernetes clusters use NFS over raw block storage?
Raw cloud block storage volumes can usually attach to only one virtual host machine at a time in read-write mode (ReadWriteOnce). NFS supports native multi-client sharing (ReadWriteMany), enabling dozens of identical application containers spread across different cluster nodes to access, append, and modify the same directory hierarchy simultaneously without re-architecting the application for object storage APIs.
What triggers an "NFS: Stale file handle" error?
An ESTALE error occurs when an NFS client attempts to access a file or directory using an internal file handle that no longer exists on the host server. This typically happens when another user or process deletes, truncates, or replaces the underlying file directly on the storage server while the client still holds an active descriptor pointing to the obsolete inode.
The Staying Power of a Forty-Year-Old Protocol
Software protocols rarely survive forty years of hardware transformation. Technologies that dominated computer rooms in 1984, token ring networks, serial cables, floppy interfaces, exist now only as museum artifacts. Network File System avoided obsolescence through relentless pragmatic adaptation.
By discarding the brittle statelessness of its youth, consolidating its network footprint to single-port TCP architectures, and incorporating parallel striping, NFS moved smoothly from local departmental labs to multi-zone cloud regions. It persists because it resolves a timeless tension: developers want local filesystem semantics, while system administrators need centralized, scalable durability. As long as software depends on standard POSIX directory operations, NFS will continue to serve bytes reliably across the wire.
