Instagram Outage Update: Story Reloads and Feed Refresh Errors Surge
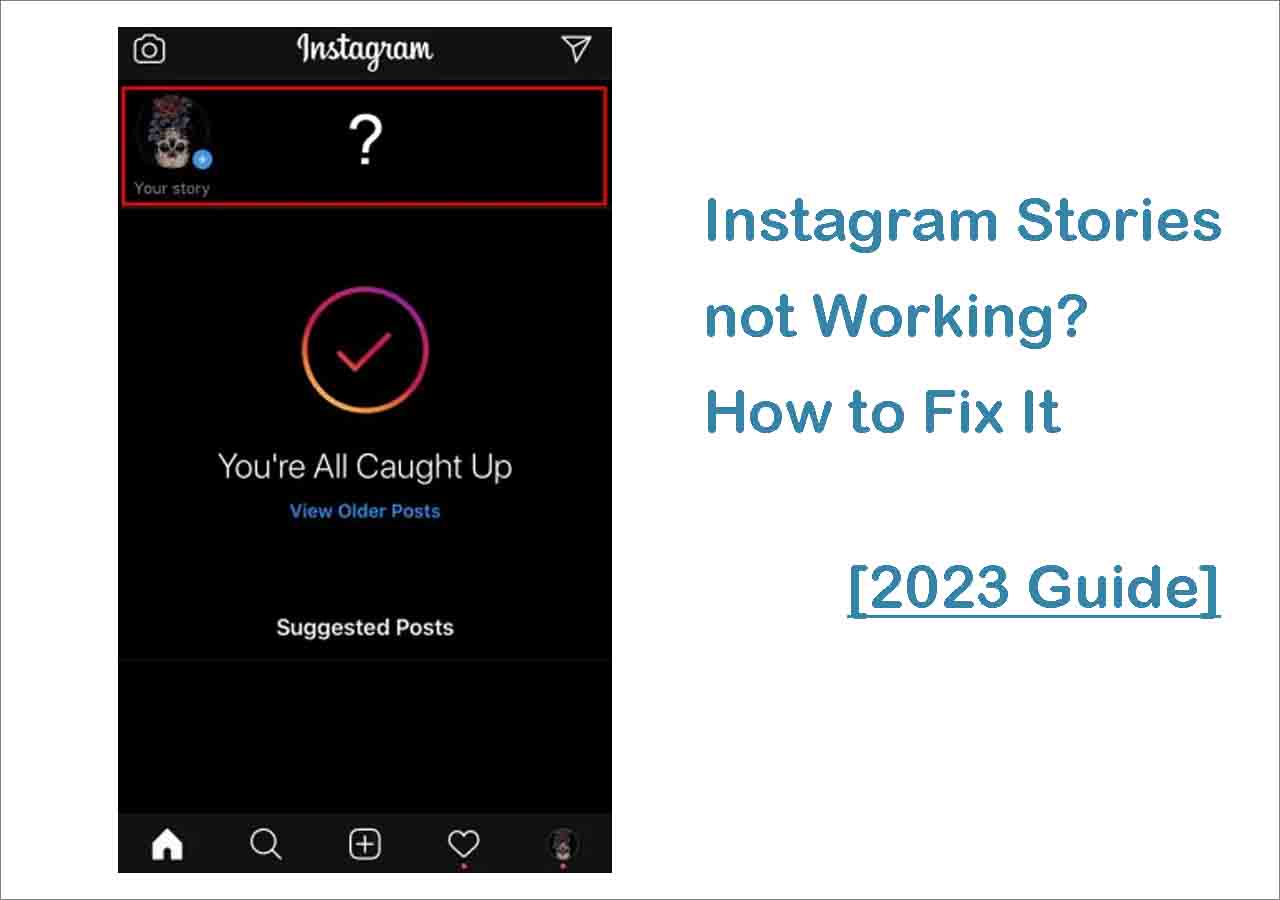
Millions of smartphone screens went blank or froze on endless looping animations as an unexpected infrastructure collapse crippled Instagram and its sibling apps across multiple continents. Users attempting to view ephemeral posts found themselves trapped in a continuous Instagram story reload loop, while the primary feed stalled behind a stubborn "couldn't refresh feed" banner. As confirmed by The Jerusalem Post Report, the breakdown cascaded through Meta's centralized infrastructure, taking down core functionalities across Facebook, Messenger, and Instagram simultaneously.
The disturbance began triggering alarms early in the morning when user reports spiked exponentially across real-time diagnostic trackers. What initially appeared to be an isolated story playback glitch on localized cellular networks quickly escalated into a documented global service disruption. Outage aggregation sites recorded unprecedented traffic spikes, leaving content creators, corporate brands, and everyday users locked out of basic engagement channels for hours.
📌 Quick Summary:
- The Core Event: A massive internal networking failure triggered widespread Instagram story reload failures and disabled feed updates across the globe.
- The Technical Cause: Edge routing misconfigurations prevented mobile clients from handshaking with Meta's distributed media delivery clusters.
- The Current Status: Core delivery protocols are stabilizing, with engineers rolling out client-side updates to resolve cached token corruption.
How the Story Playback Glitch Paralyzed Accounts Worldwide
The breakdown manifested with deceptive simplicity on mobile devices. When users tapped on the colorful rings encircling profile pictures at the top of their screens, the application either displayed a spinning loading ring or bounced immediately back to the home tray. Attempts to pull down to refresh only worsened the problem, surfacing the dreaded feed refresh error across both iOS and Android builds.
Behind the interface, the app was failing to complete basic HTTPS handshakes with Meta's media delivery servers. The client requested short-form video chunks and static images that the edge infrastructure could not locate or route. Instead of returning a clean error code that prompted a single pause, the app entered a retry storm, repeatedly pinging upstream gateways until local device threads throttled execution entirely.
Social feeds on alternative platforms quickly filled with complaints from creators whose scheduled campaign rollouts hit a wall. Influencers who rely on sequential story segments discovered that earlier frames vanished while later frames refused to render, destroying chronological narratives and engagement metrics during peak monetization hours.
Inside Meta's Infrastructure and the Root Networking Failure
Large-scale social networks depend on deeply integrated Content Delivery Networks (CDNs) and sophisticated edge proxy architectures to serve petabytes of video data every second. When this ecosystem experiences an unhandled routing error, the effects are immediate and severe.
Internal diagnostics point toward a severe Meta network failure originating within border gateway protocols and internal routing tables that govern cross-datacenter traffic. Rather than a routine application bug that an over-the-air client patch could fix, the root breakdown severed the link between localized edge servers and backend user-session stores. As authentication tokens expired or failed validation against disconnected data layers, client applications could not confirm that users possessed permission to stream requested media.
The downstream effect spread across the entire ecosystem. Messenger suffered direct connection dropouts, preventing real-time message synchronization. Facebook profiles failed to render media attachments, and Instagram's media pipeline ground to an effective halt. Because the mobile client repeatedly tried and failed to authenticate each media asset, the local software cached broken session states, meaning the glitch lingered on consumer devices even after core datacenters began recovering.
Tracking the Outage Wave Across Global Datacenters
Independent telecommunications tracking platforms registered a sharp, synchronized anomaly. Starting across the Middle East, parts of Europe, and South Asia, reports surged within minutes, followed swiftly by a wave of alerts as North American users woke up to unyielding error messages.
| Incident Phase | DownDetector Volume Surge | Primary Failure Mode |
|---|---|---|
| Phase 1: Initial Anomaly | +340% baseline increase | Media caching failure; story assets freeze at 0:00 timestamp. |
| Phase 2: Global Cascade | +1,850% baseline increase | Total session timeout; feed refresh error strikes active feeds. |
| Phase 3: Partial Recovery | +420% residual baseline | Backplane routing stabilizes; client cache corruption persists locally. |
| Phase 4: Full Stabilization | Normal baseline levels | Media endpoints restored; patch deployed to prevent client loops. |
Regional telecommunications providers in the United Arab Emirates, India, and Israel documented widespread drops in outbound social traffic to Meta IP ranges, confirming that data requests never cleared central transit points. Simultaneously, platforms like X experienced historic surges in user searches for phrases such as "Instagram stories not loading" and "Instagram server status."

Distinguishing Centralized Server Outages from Local Client Glitches
Navigating widespread digital disruptions requires separating cloud-side breakdowns from individual device hardware or connection problems. Many users waste time resetting home routers or reinstalling operating software when the fault sits squarely within upstream servers.
Network-wide server issues leave clear footprints:
When an outage is centralized, the application opens normally, but dynamic data elements remain empty or generate immediate timeout warnings. Other web-connected applications continue to function perfectly at full bandwidth, while Meta-specific services simultaneously malfunction. Cellular data and Wi-Fi networks return the exact same loading hang, and public status boards show thousands of identical geographic complaints.
Isolated local device problems behave differently:
Local faults often trigger sudden, hard app crashes directly to the home screen rather than looping network retries. High local storage usage, corrupted background cache files, or out-of-date application packages generally degrade device-wide performance rather than freezing specific API endpoints while leaving textual feeds intact.
Immediate Troubleshooting Steps While Meta Deploys Server Patches
When engineering teams resolve routing discrepancies on production backends, client apps do not always update automatically. Residual cache files frequently trap the app in a broken state. Taking tactical remediation steps can clear bad session data and restore normal playback.
Android users should prioritize an immediate app cache clearing sequence. Navigating through Settings, selecting Apps, locating Instagram, and choosing Storage allows users to clear cache files without deleting login credentials or downloaded media. This forces the device to abandon broken temporary tokens and request fresh routing tables from operational edge gateways.
Apple iOS users face a more rigid file system architecture that does not feature an exposed cache-clearing toggle. In this case, offloading the app via iPhone Storage settings or performing a clean delete and reinstall purges the lingering state data that sustains playback loops. Forcing an immediate app update through the App Store ensures your device runs the latest network retry patches Meta pushes during major incidents.
Frequently Asked Questions (FAQ)
Q1: Why does my Instagram story continuously reload without ever playing the video?
A1: This occurs when the mobile app successfully pulls the visual thumbnail from local memory but fails to secure the actual video stream from Meta's edge servers. The client enters an automated retry loop, restarting playback from the beginning each time the media connection times out.
Q2: Does clearing the Instagram cache delete my saved drafts, archives, or chats?
A2: Clearing your cache only purges temporary media assets, scripts, and preloaded images. Your direct messages, account details, and published story archives remain safely preserved on cloud servers. However, clearing all app data on Android will require you to log back into your account.
Q3: How can I verify whether Instagram is down for everyone or just me?
A3: Cross-check real-time aggregator tools like DownDetector, inspect official engineering communication channels, or test sibling platforms like Messenger and Threads. If multiple Meta services stall while unrelated video streaming apps run smoothly, the problem stems from Meta's central network.
Engineering Meta's Resilience in an Interconnected Web
The latest sequence of service interruptions exposes the fragility of consolidating global communications across shared infrastructure backplanes. When Facebook, Messenger, and Instagram depend on the same routing fabrics and identity clusters, a single configuration mistake ripples out to hundreds of millions of screens at once.
Meta's engineering units continue hardening cross-region failovers to stop localized edge misconfigurations from cascading into global operational blackouts. Until client applications learn to handle disconnected states more gracefully without entering continuous reload loops, users will continue bearing the visible brunt of deep infrastructure breakdowns.